Label Studio
Timeline
2023.09 - 2023.12
Team
1 designer (me), 1 PM, 6 SDEs
Company
eBay, Payment & Risk
Role
Research, Design, Prototyping, Testing
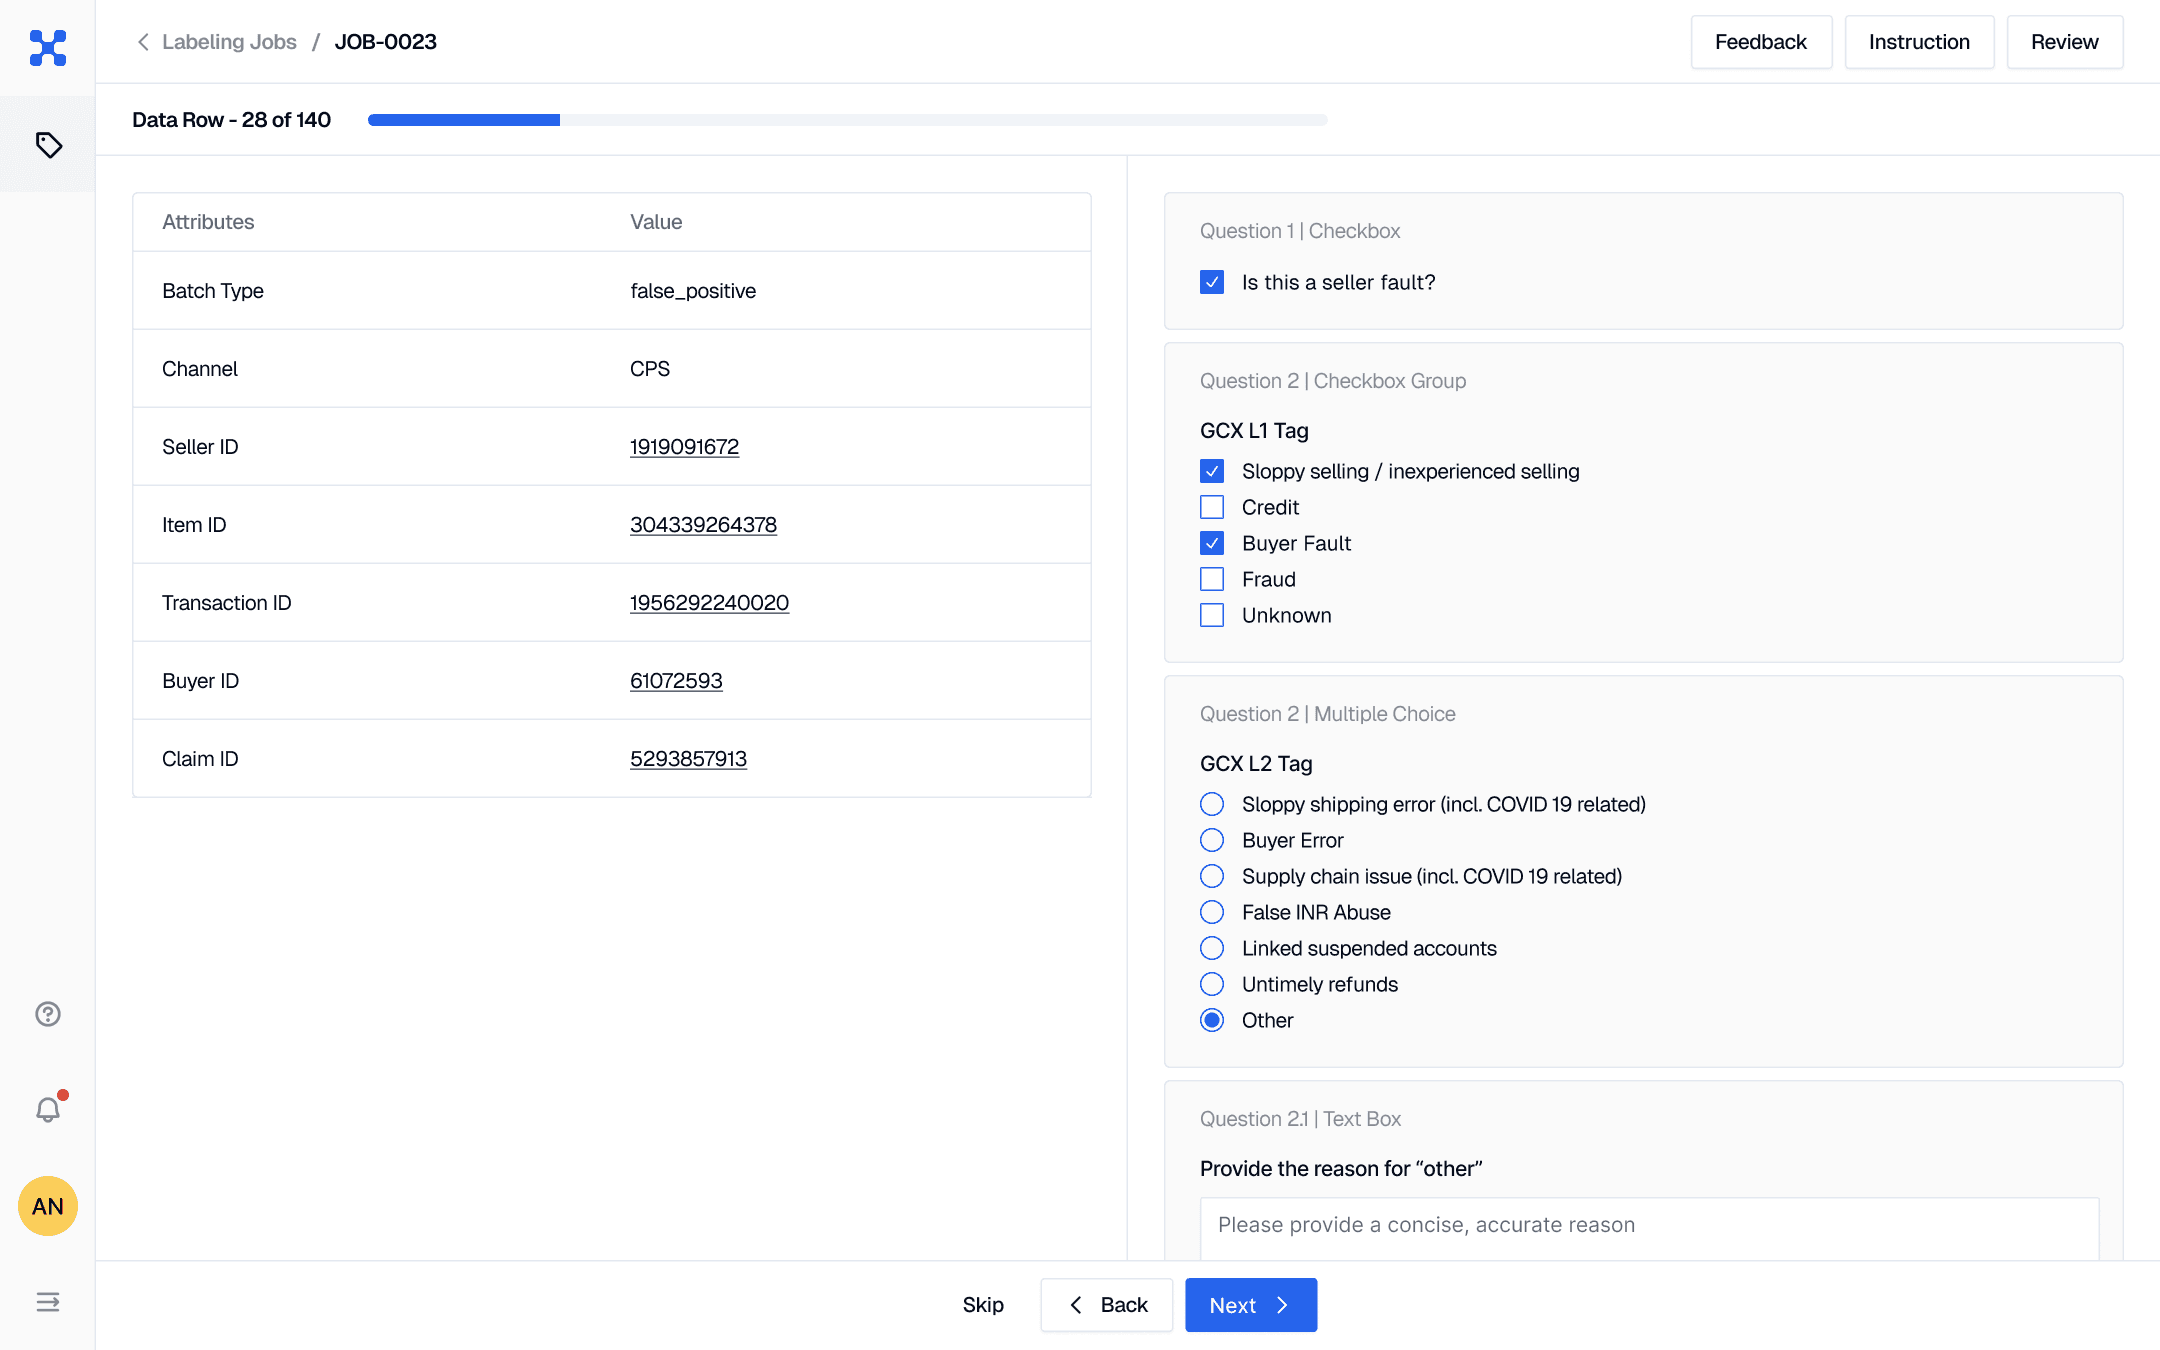
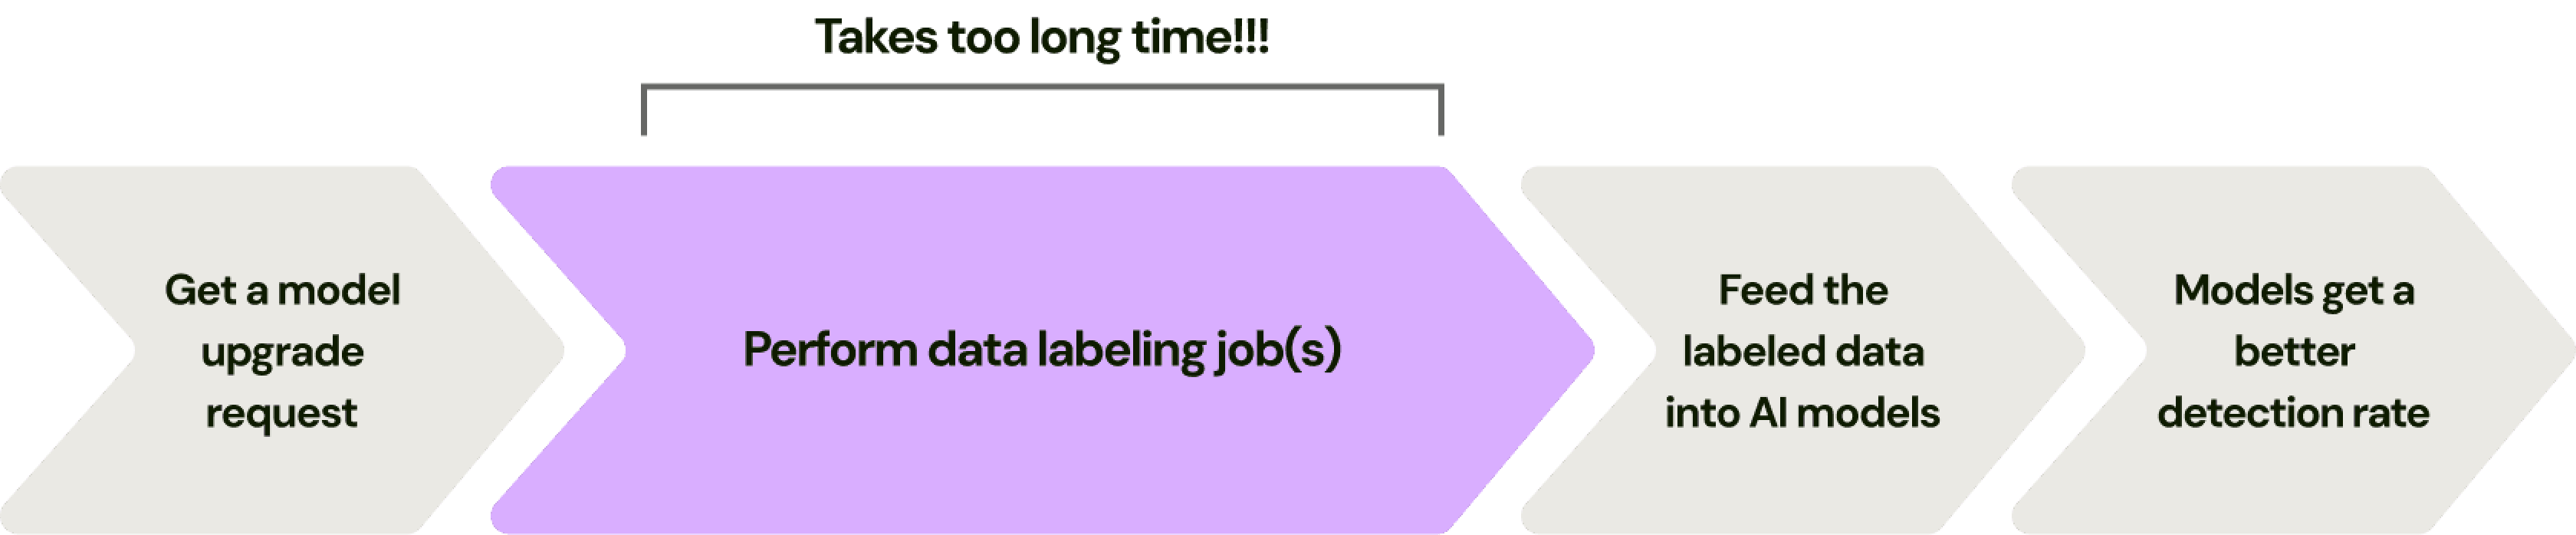
At eBay's Payment & Risk team, the data labeling workflow was hindering the timely updates and effectiveness of our detection AI models. Recognizing this critical bottleneck, our team took ownership and spearheaded the development of Label Studio from the ground up, a strategic initiative to revolutionize our data labeling workflows.
Impact
CPH (Completions Per Hour)
+46%
Labor Cost per Case
-33%
Satisfaction Rate from Post-survey
9.8/10.0
Cumulative Labeled Data in platform
100k+
Problem
Slow & inefficient labeling delays AI updates
Data labeling significantly impacts our AI model training cycles. Frequent feedback from data scientists indicated that lengthy labeling processes delayed critical model updates, posing potential risks to eBay’s financial security.
Why this problem?
Auditing our current process
To better know the reasons behind this problem, my first steps is to carefully review & evaluate our team’s current solution.
#1 Collaboration among three distinct roles
I first consulted our PM, who closely interacts with the labeling team, to clearly define our target users. This foundational understanding shaped the direction for subsequent observation studies and interviews.
Data Scientist
“I create the labeling jobs and analyze labeled data to train AI models.”
Admin
“I will preview pending jobs & assign them, and I will track them to keep them on schedule.”
Annotator
“I will perform the assigned data labeling job following the given instructions.”
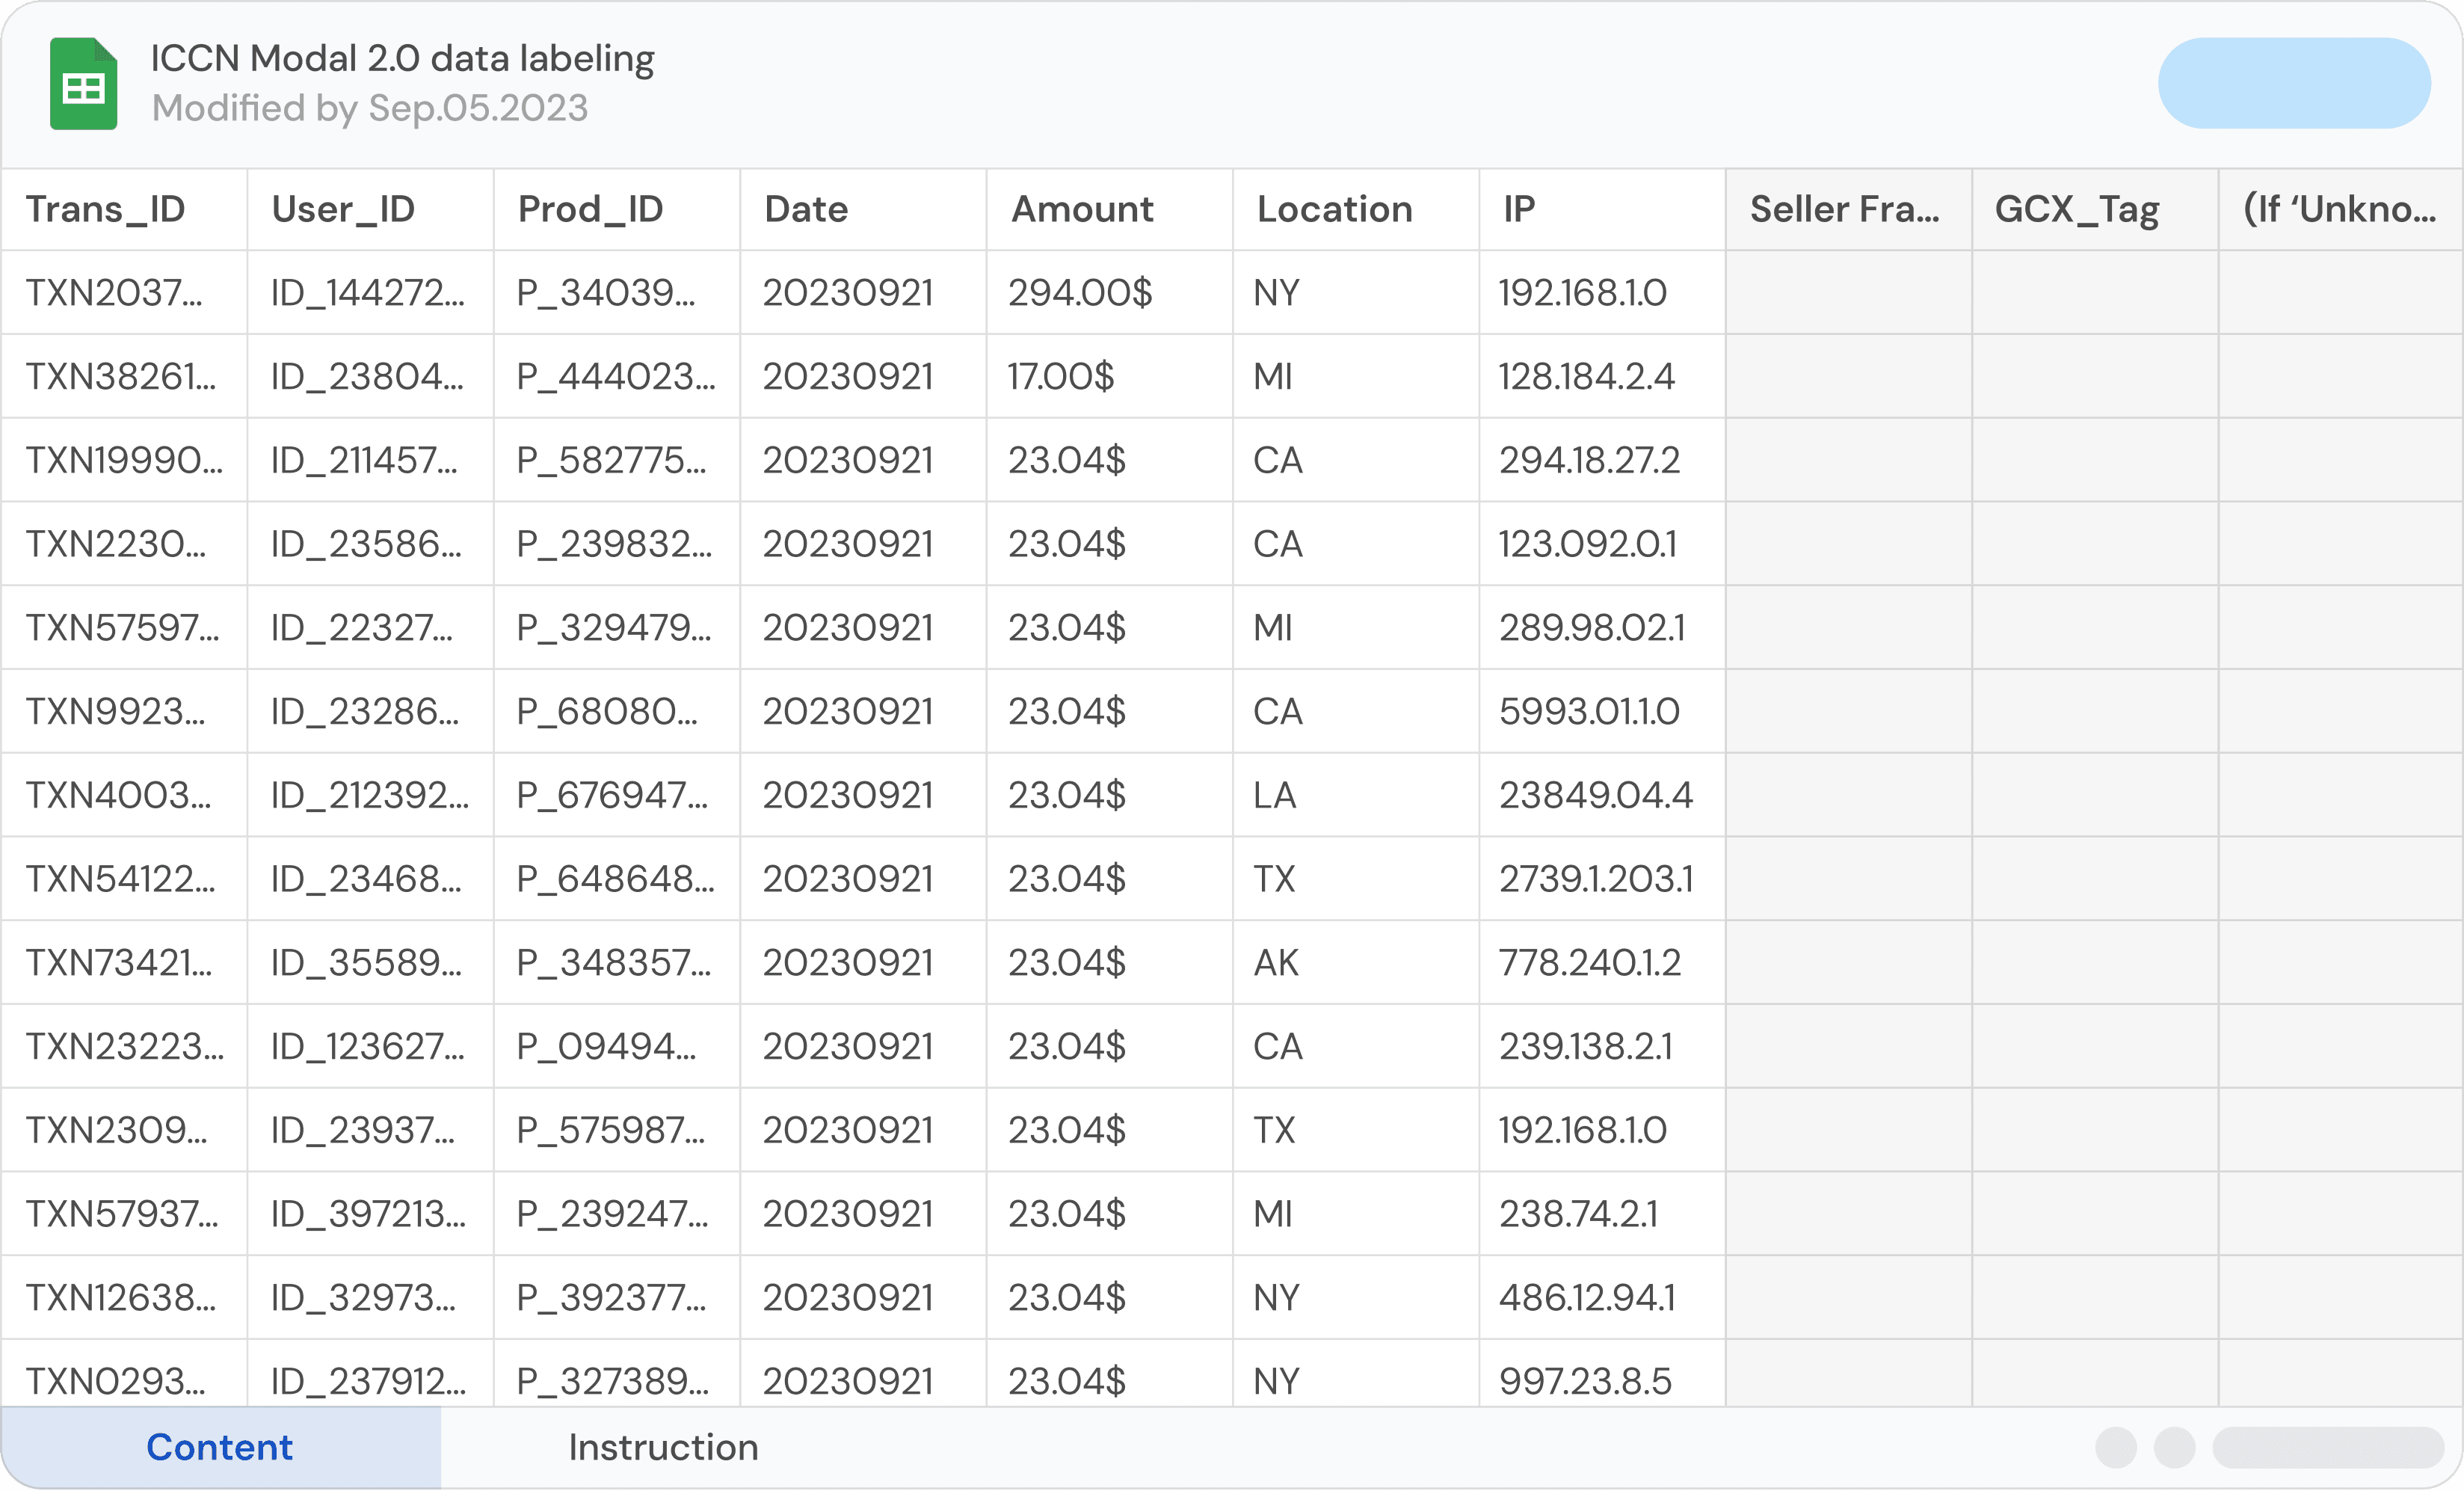
#2 Excel, the primary tool, was unsuitable for labeling tasks
Reviewing existing Excel-based workflows, I identified several usability and efficiency issues:
High Data Volume
Each labeling job included ~ 120 rows of data, with ~12 data points per row.
Repetitive Jobs
The jobs aim to train the same model share the same instruction & problems, differing only in the data samples.
Cluttered Display
Data is packed row by row, and long text is often cut off, making it hard to read and scan.
Disrupted Flow
Annotators constantly switched screens for instructions & details, causing inefficiencies and errors.
Observation Study & Interviews
Understanding each role’s pain points
To dive deeper, we conducted remote observation sessions and interviews to pinpoint specific inefficiencies and user needs.
Observation Study & Interview Insights 🔍
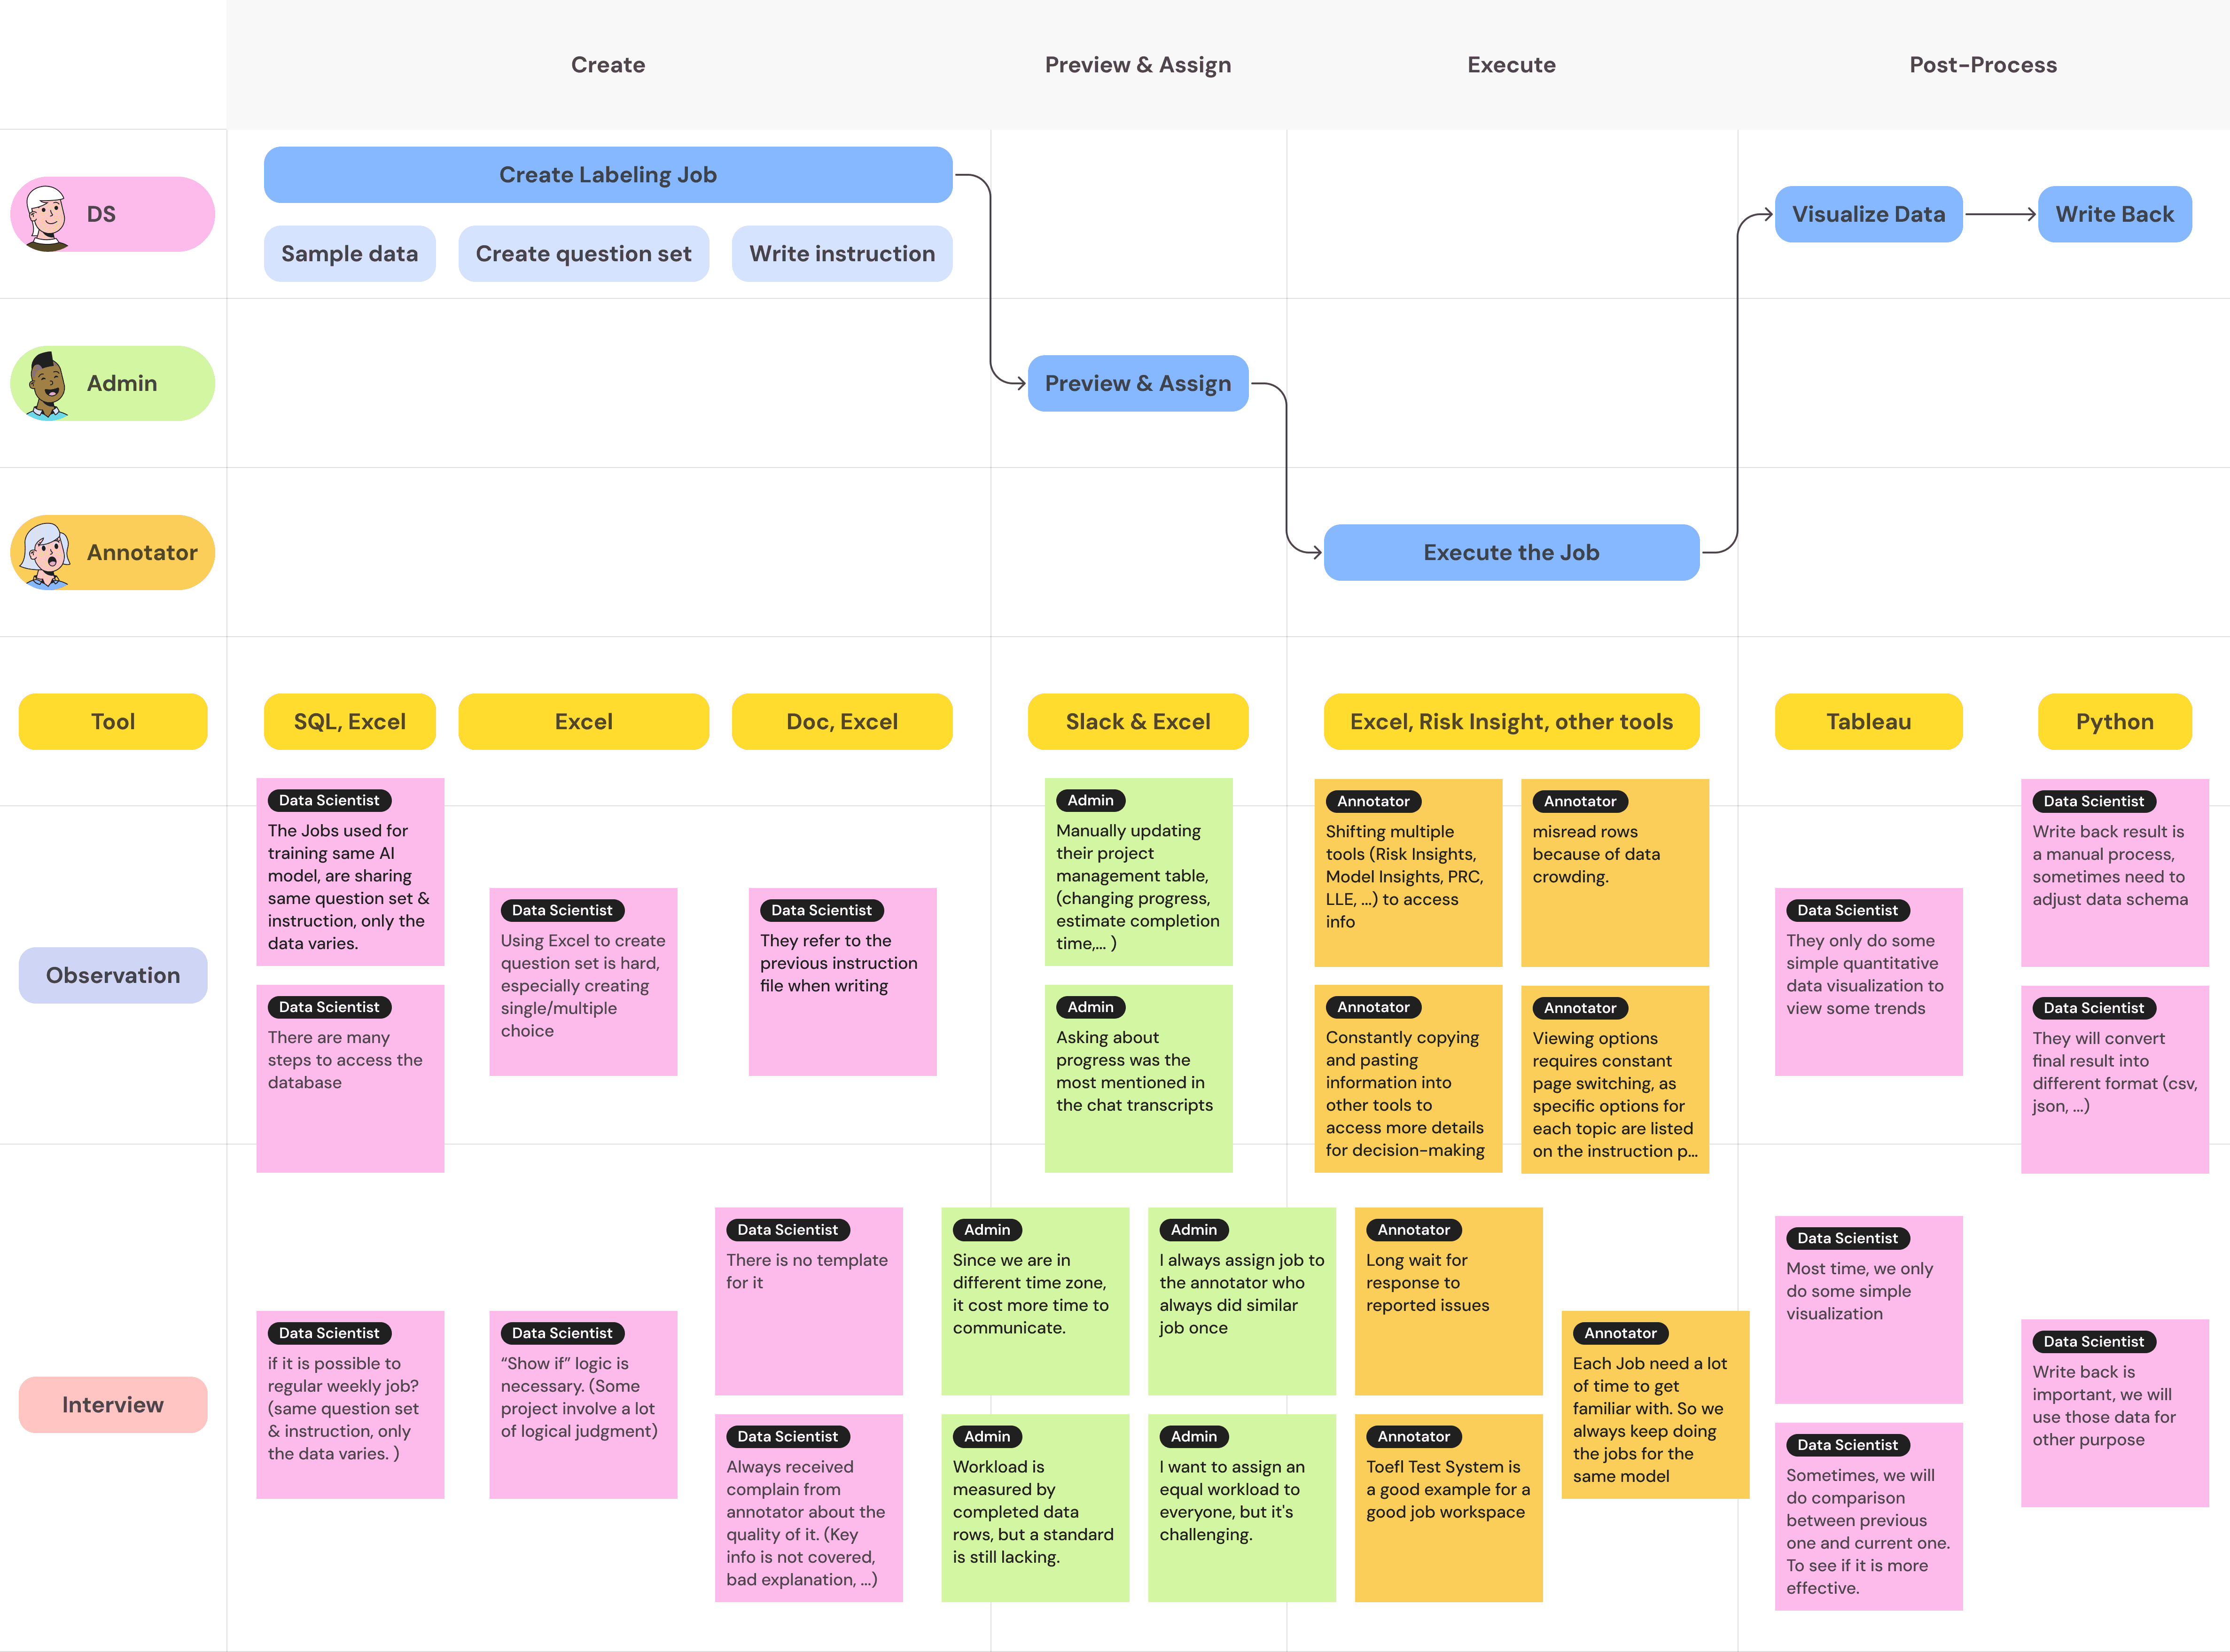
I distilled the core challenge for each role into a clear, concise statement, enabling our team members to quickly understand user needs and effectively guide our subsequent design decisions.
 data scientist
Fragmented Workflow
Their workflow requires multiple tools and steps, and some tools—like Excel—poorly suited for tasks.
AdminLow Visibility
Poor status tracking resulted in heavy communication and slow decision-making.
AnnotatorInefficient Tooling
Using Excel as the primary labeling tool leads to low efficiency and frequent errors due to poor task fit.
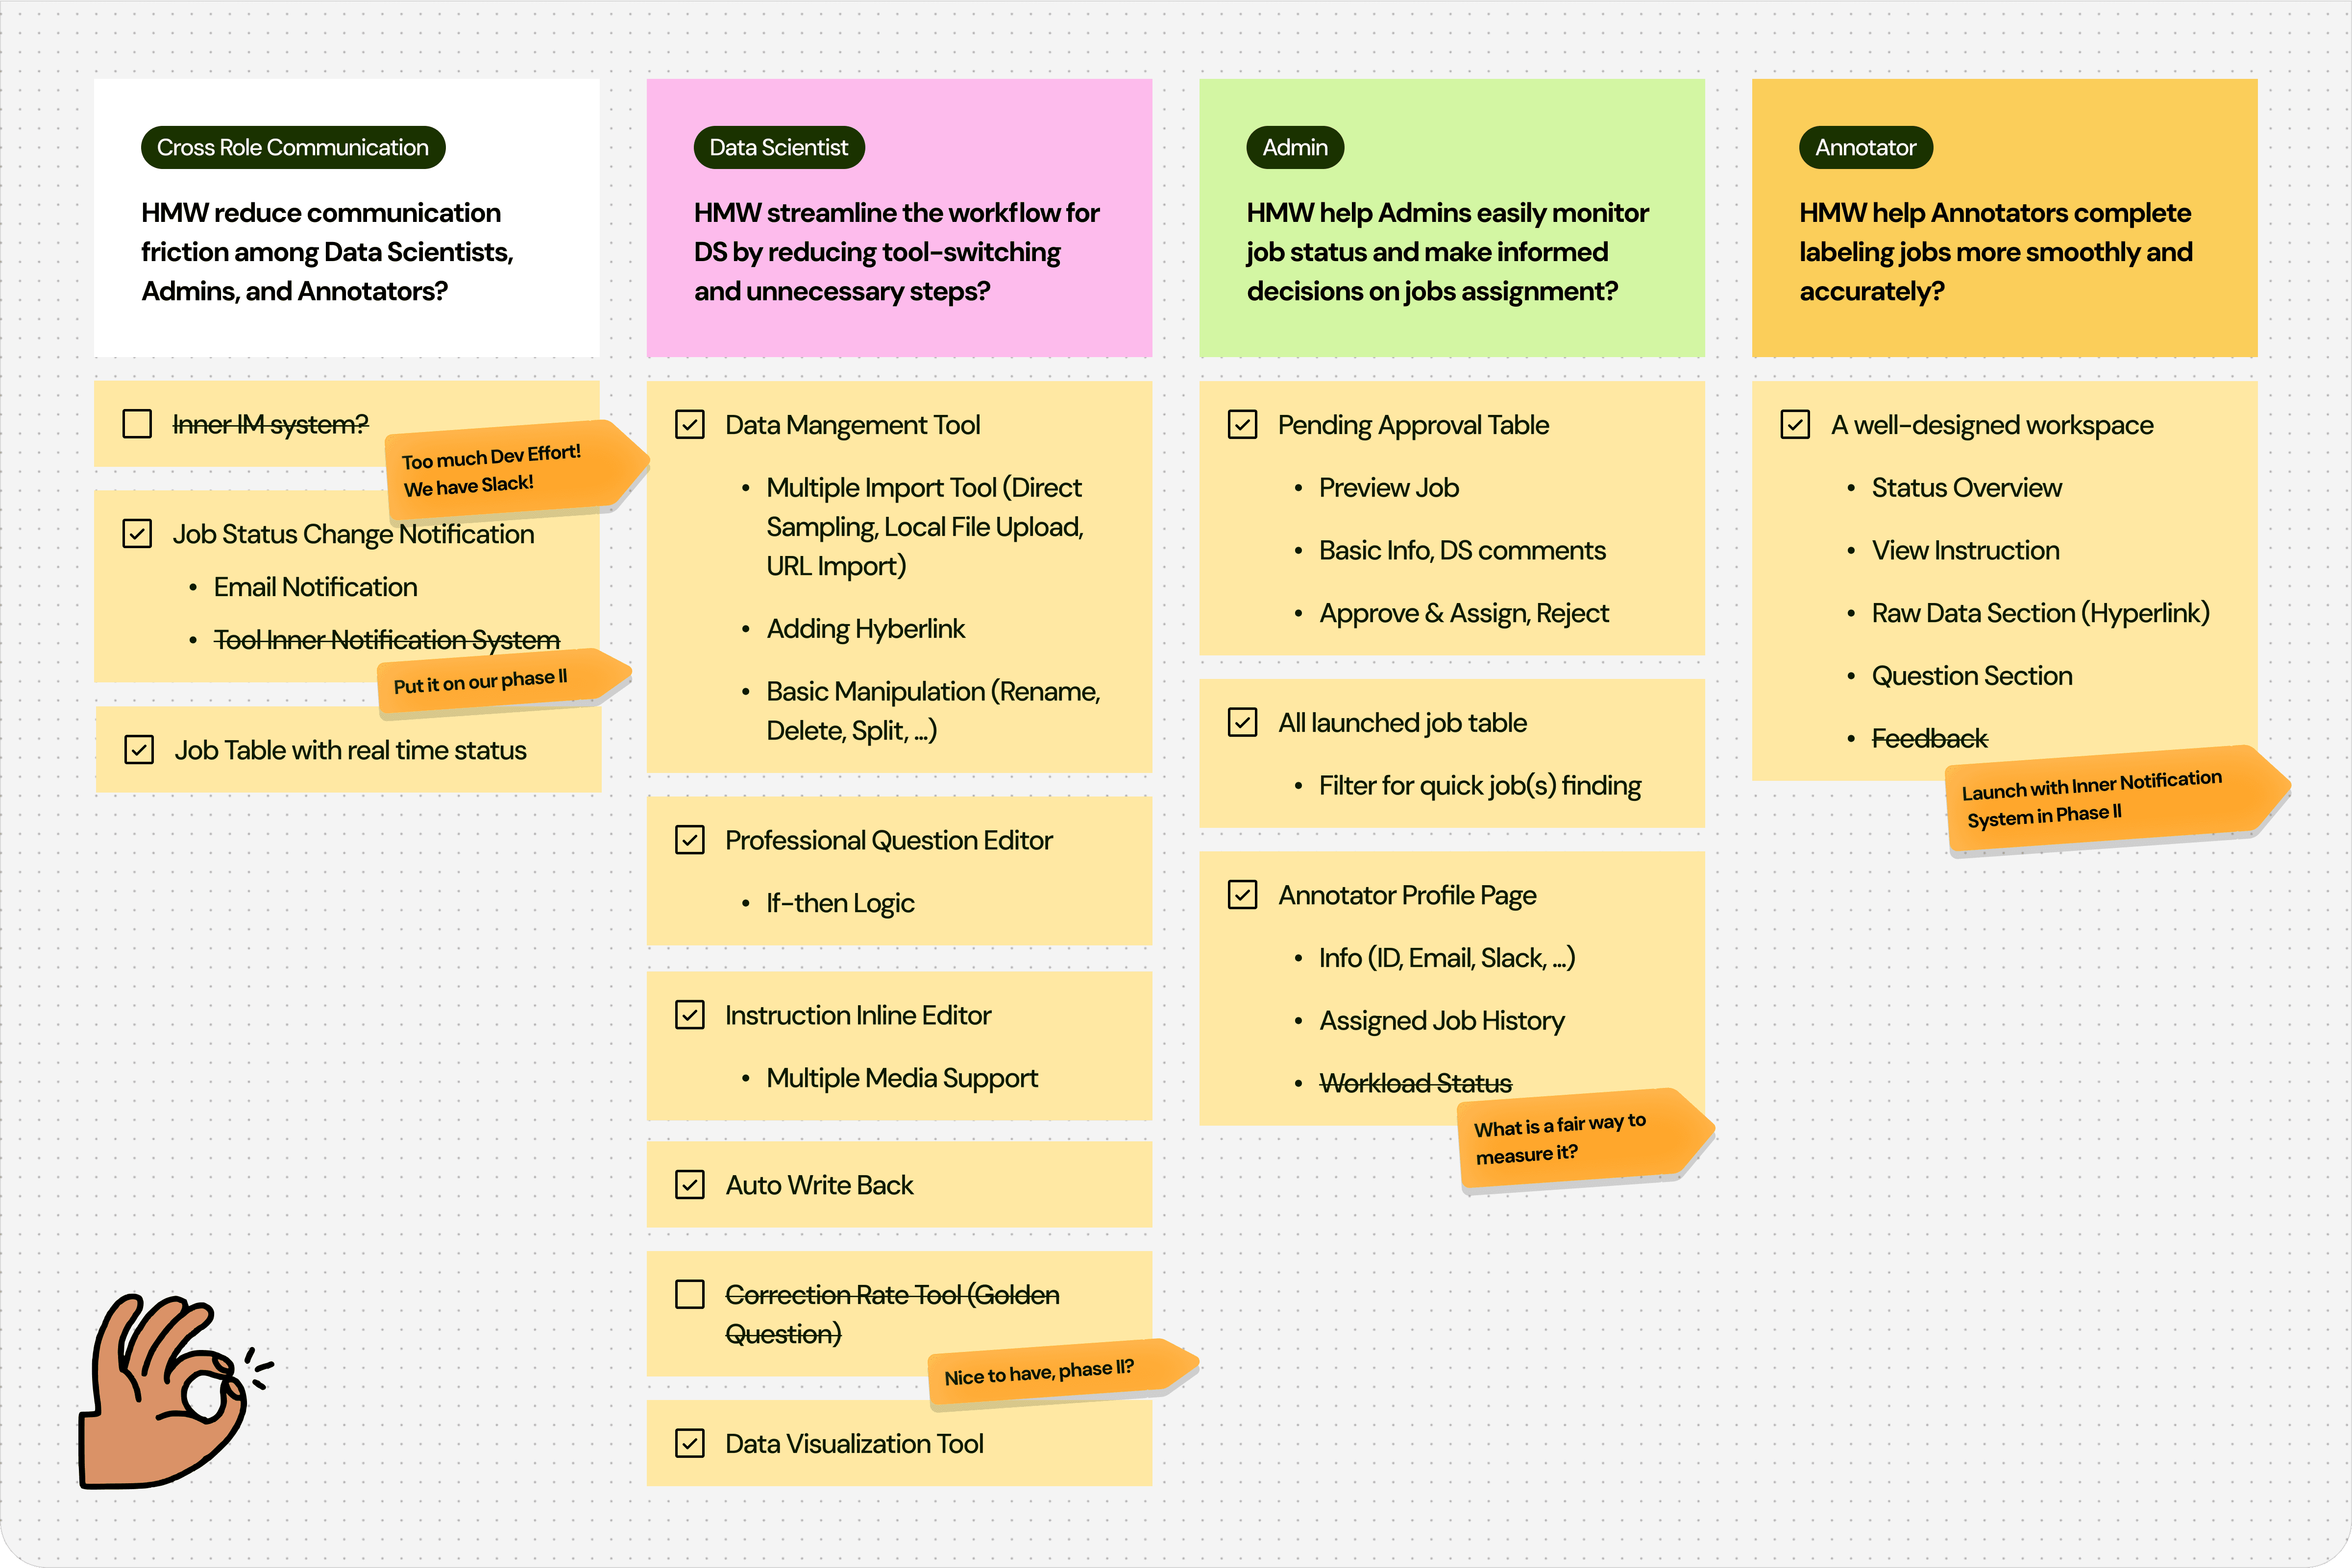
Brainstorming & Scoping
Selecting the MVP solution
After rapidly brainstorming possible solutions, I presented our options to the PM and dev team. We prioritized essential, low-effort solutions for Phase I, deferring additional enhancements to Phase II.
HMW...
User flow Map
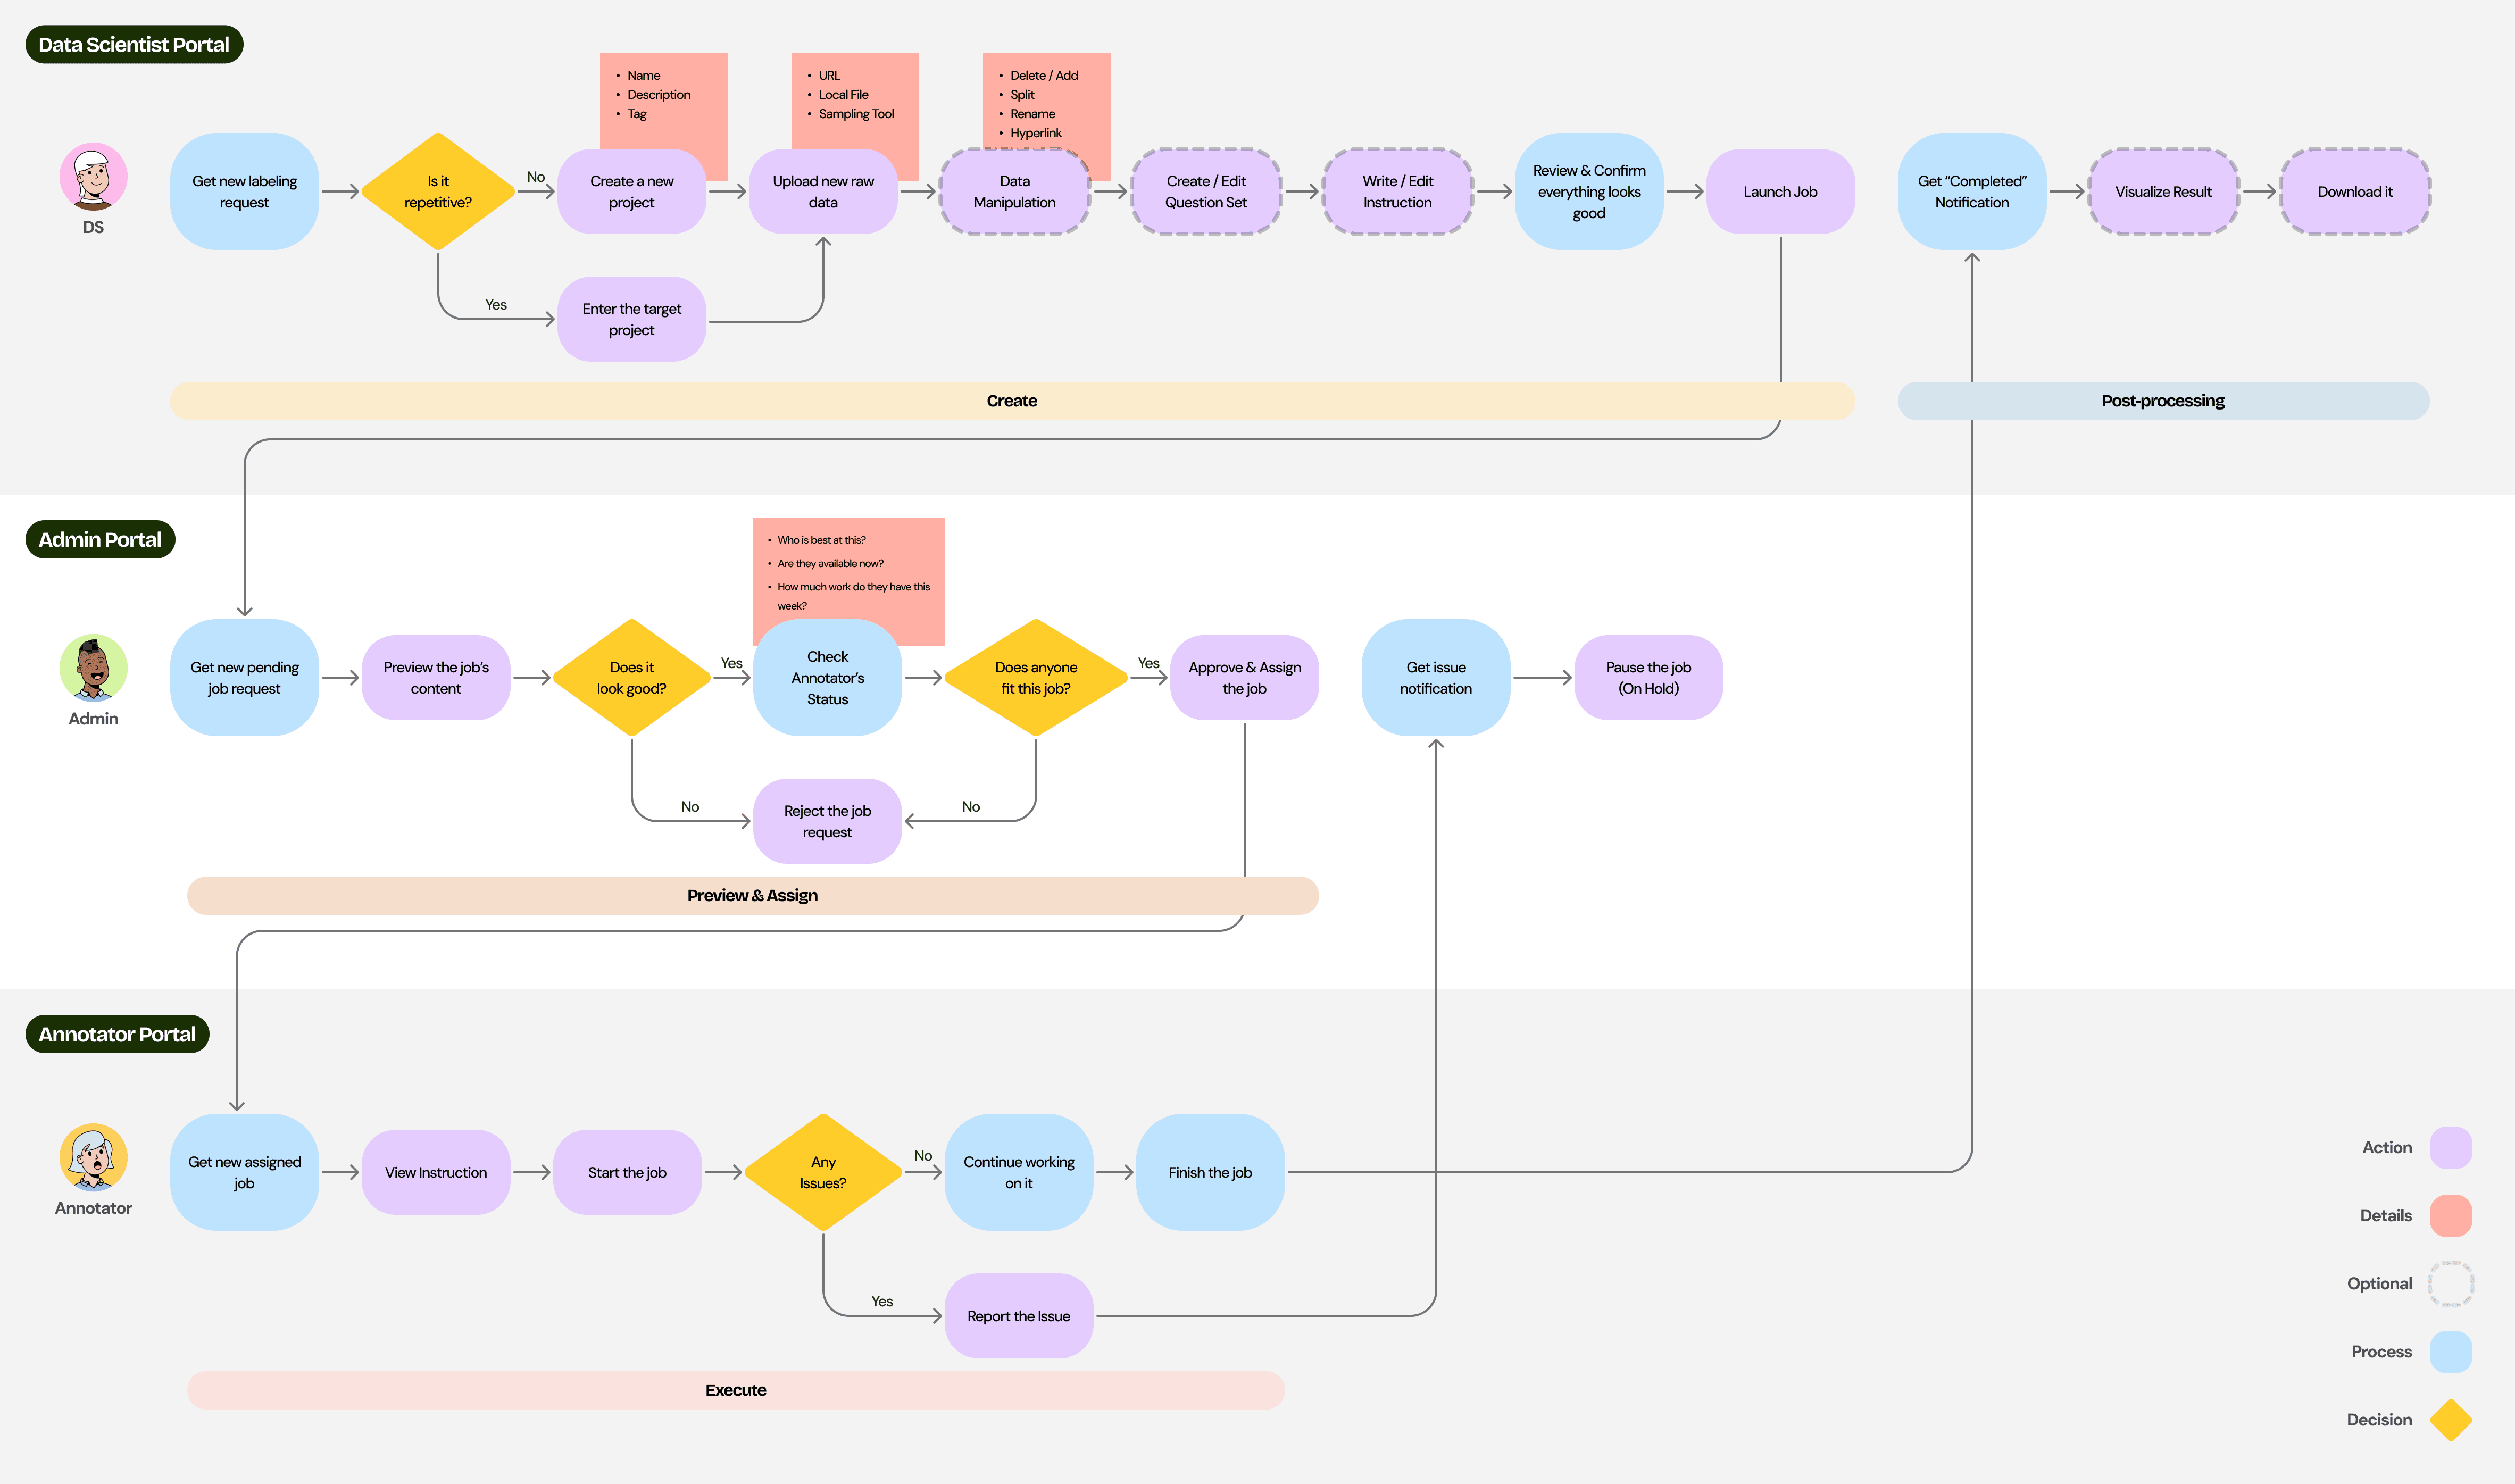
Mapping a unified user experience
To ensure Label Studio delivered a seamless experience, I mapped detailed user flows across all three roles—Data Scientist, Admin, and Annotator. Collaborating closely with our lead engineer during this process allowed us to refine and simplify the architecture, ensuring significantly reducing user steps.
User Flow Diagram
Design
Our final design for launch
Before revealing our design iterations, here's our final design. For more detailed insights into design decisions, feedback integration, and design thinking, feel free to reach out to me.
Create a project
The first step for launching a data labeling job is to create a data labeling project.
Import raw data
Previously a manual download from the transaction database & local sampling is now streamlined through direct database sampling or easy file/url uploads.
Question & instruction setup
Replacing cumbersome Excel processes, our Question and Inline Instruction Editors facilitate easy question creation and content organization.
Preview & launch a job
After uploading data and setting up questions & instructions, Data Scientists can preview labeling jobs exactly as annotators see them, then launch jobs with confidence and easily track progress.
Assign pending Jobs
Admins immediately receive pending job notifications and gain real-time visibility into annotator availability, job statuses, and jobs histories, enabling informed decisions and smoother communication.
Perform the assigned job
Assigned annotators access clear instructions in an optimized workspace, improving focus, efficiency, and overall labeling accuracy compared to previous Excel-based methods.
Iteration
Refining design through feedback
I conducted usability testing with cross-functional team members to evaluate the tool’s clarity, task completion, and overall comprehension.
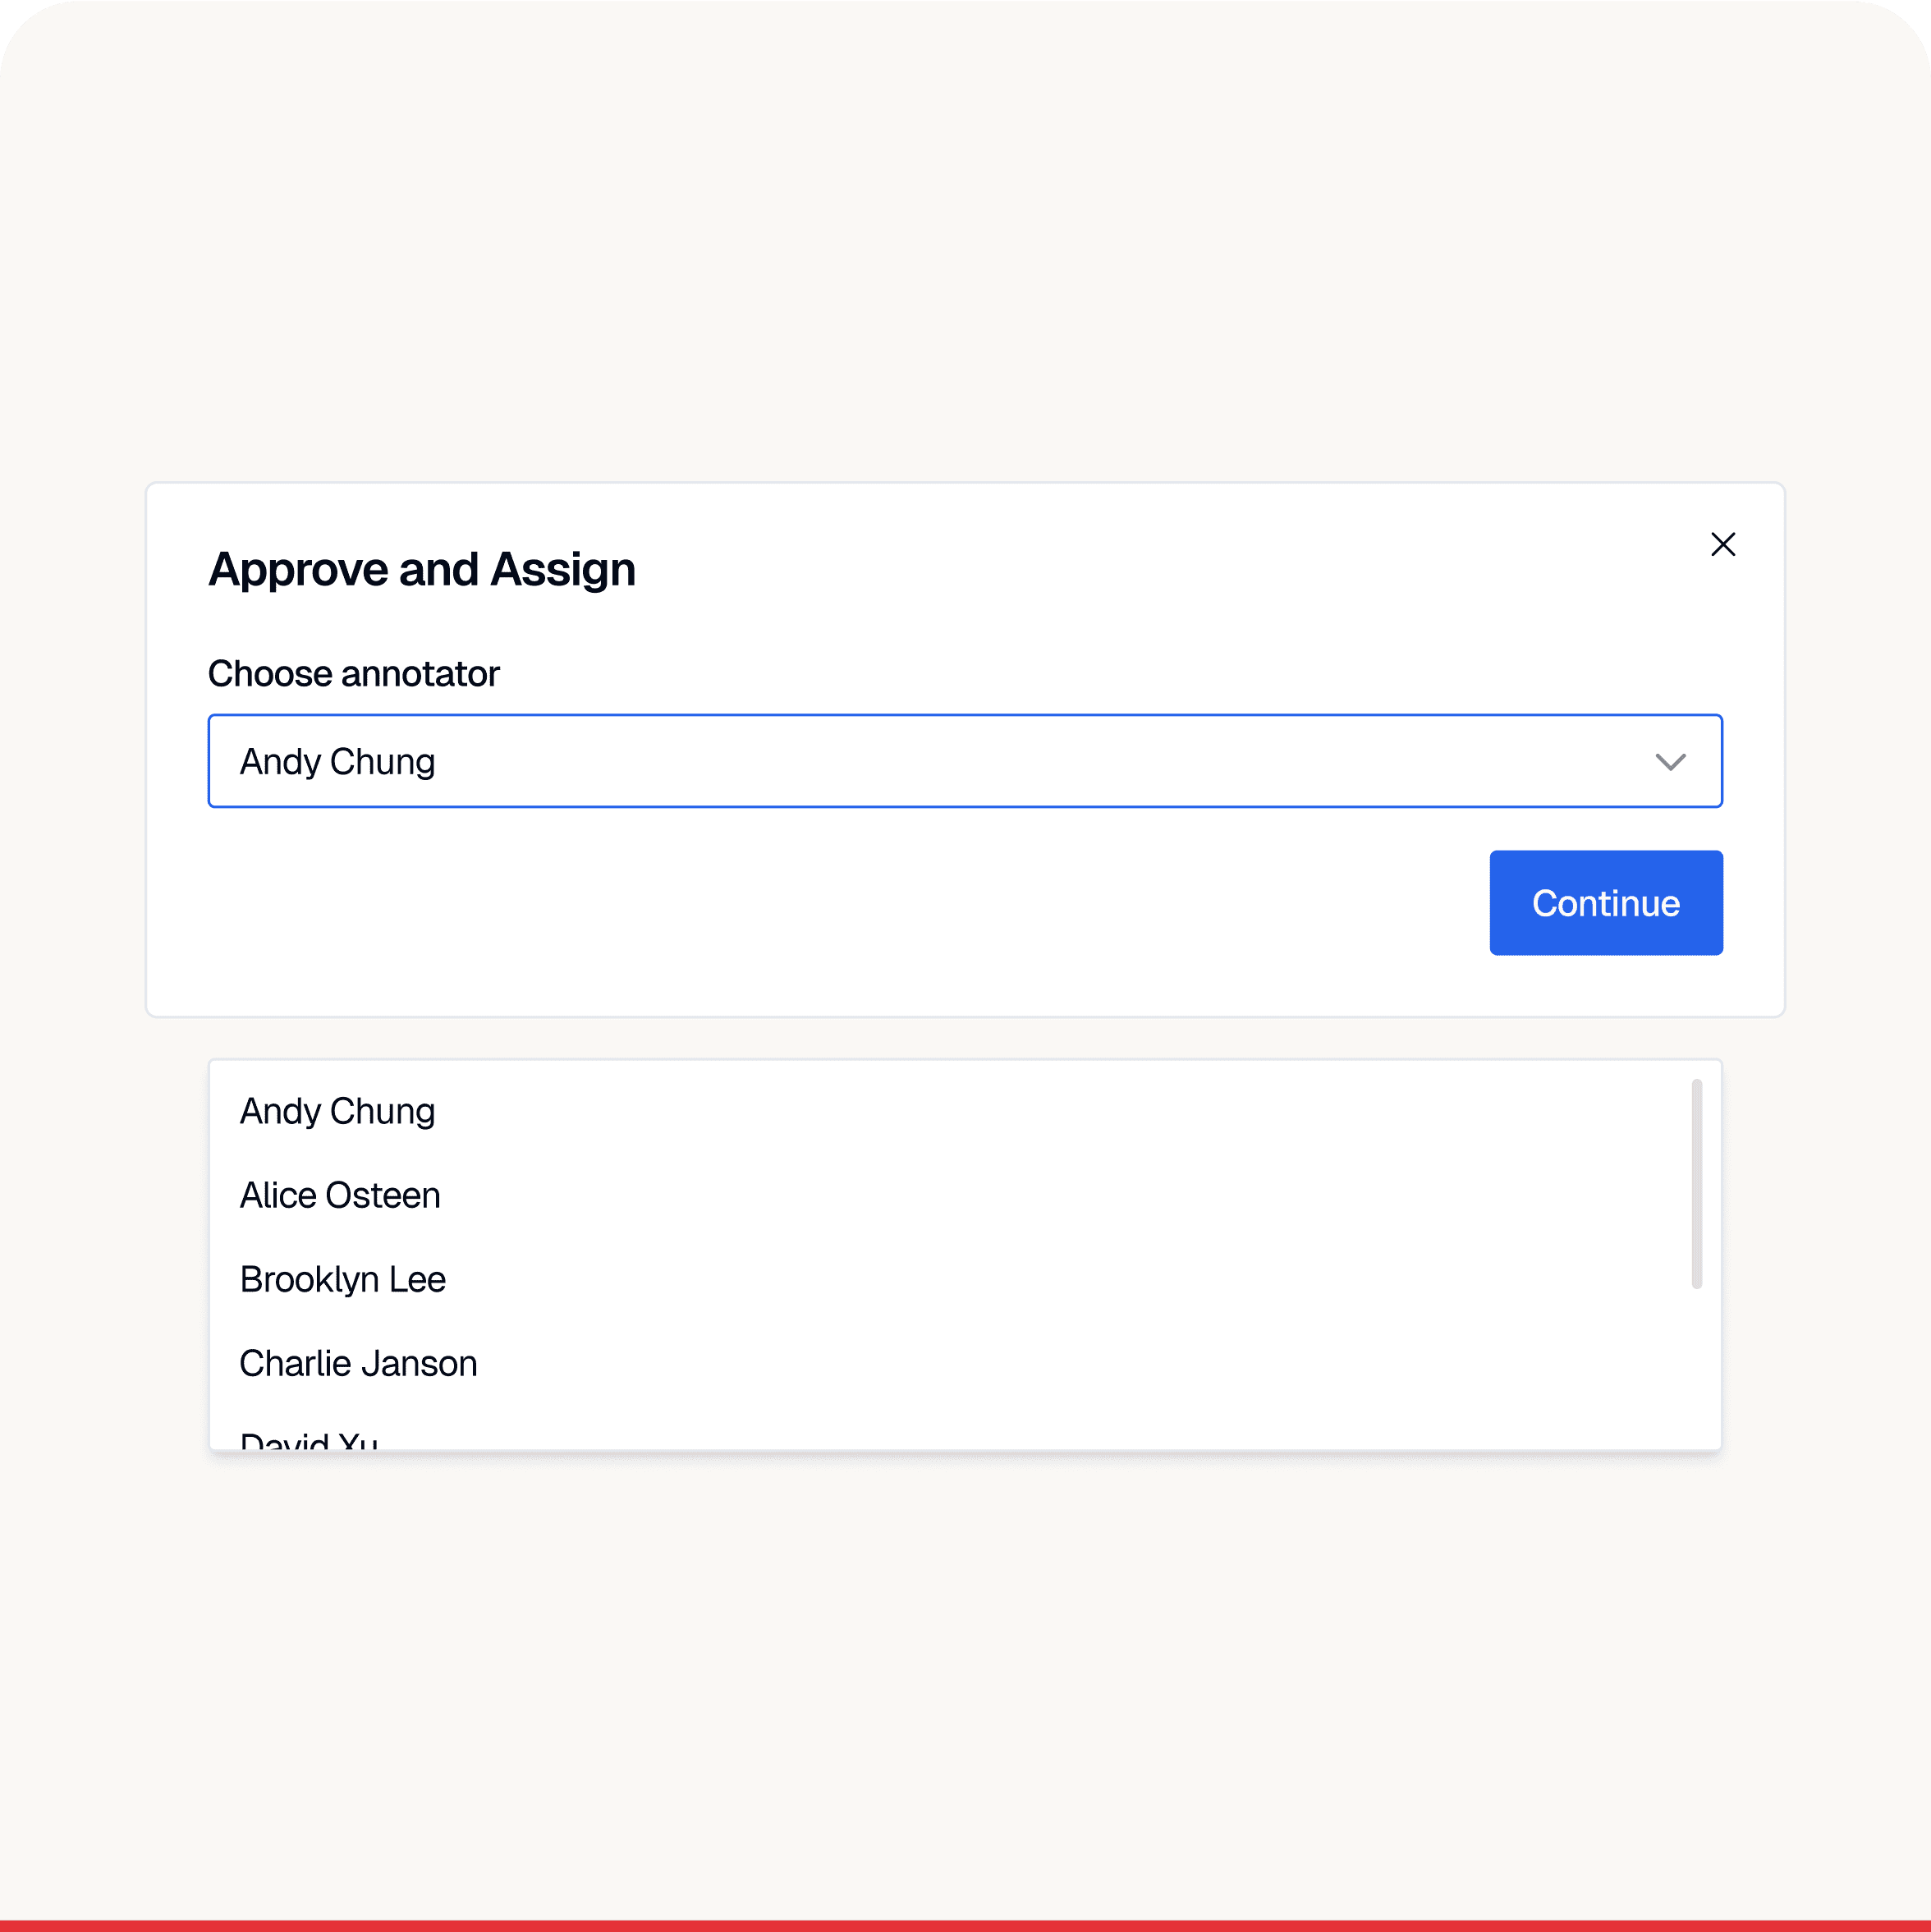
Before
Labeling jobs could only be assigned to a single annotator, making it inefficient to complete large-scale jobs.
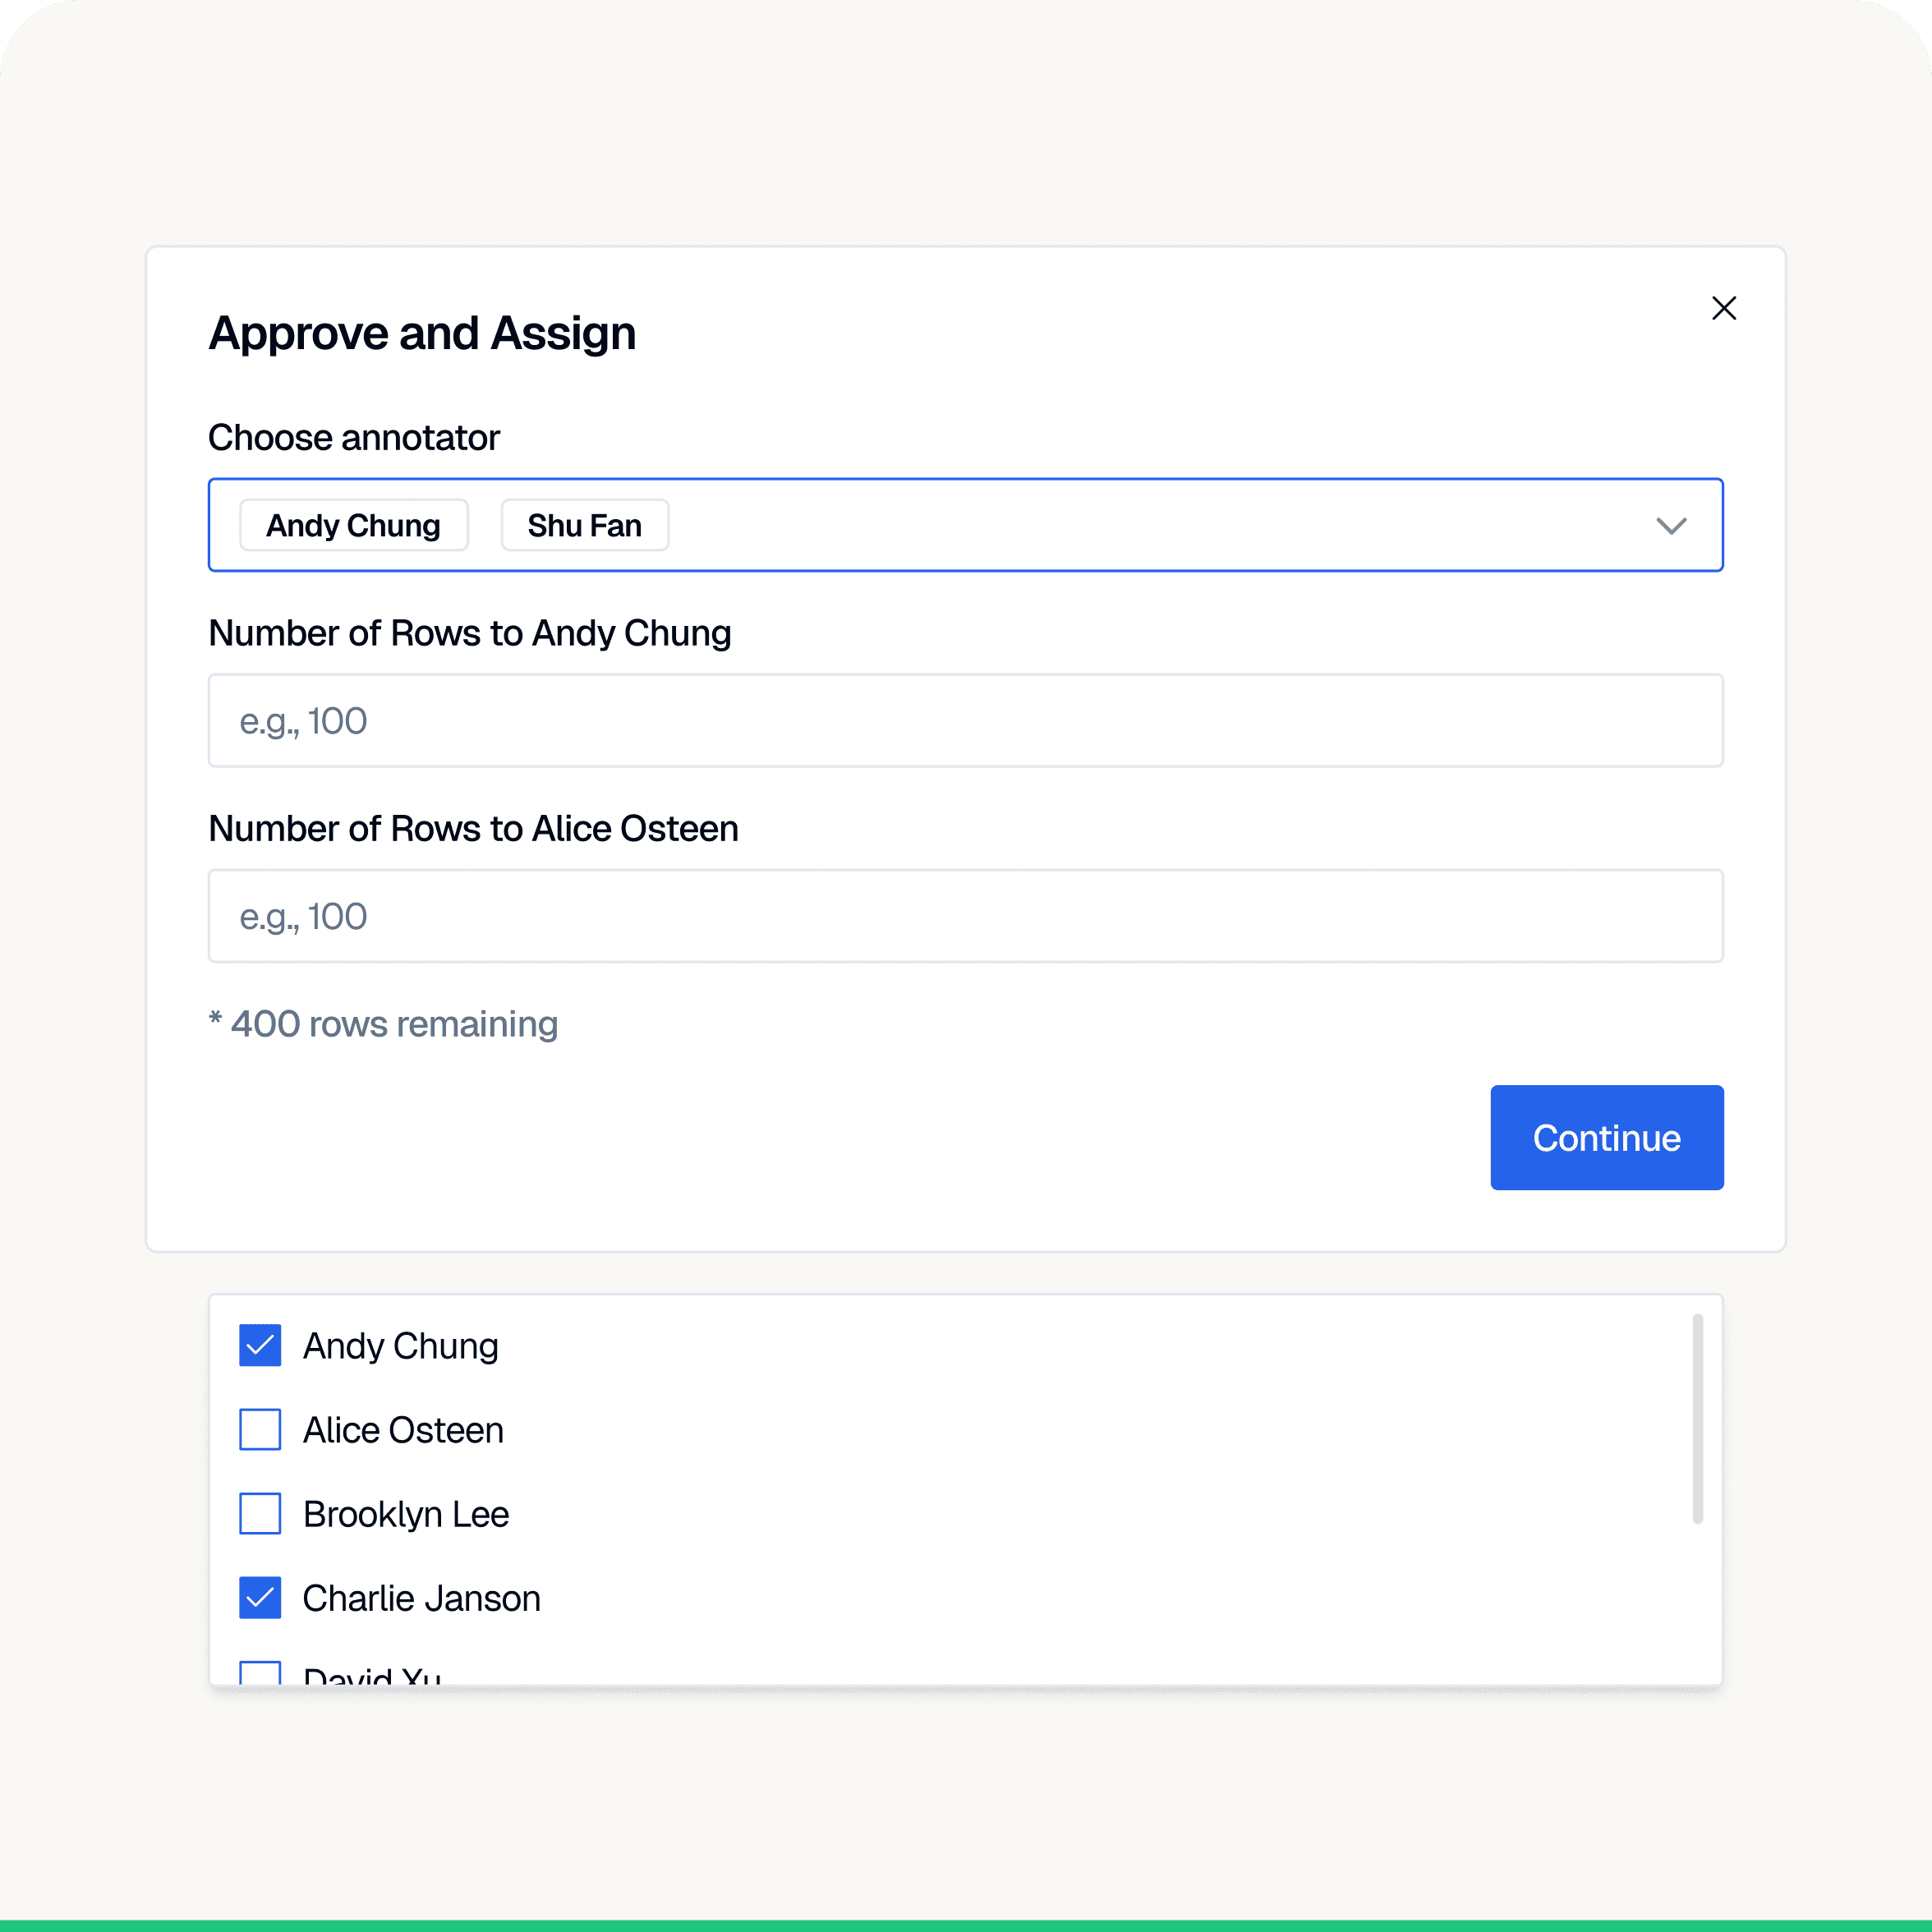
After
We enabled multi-annotator assignment, allowing jobs to be split across several annotators with a designated number of rows per person.
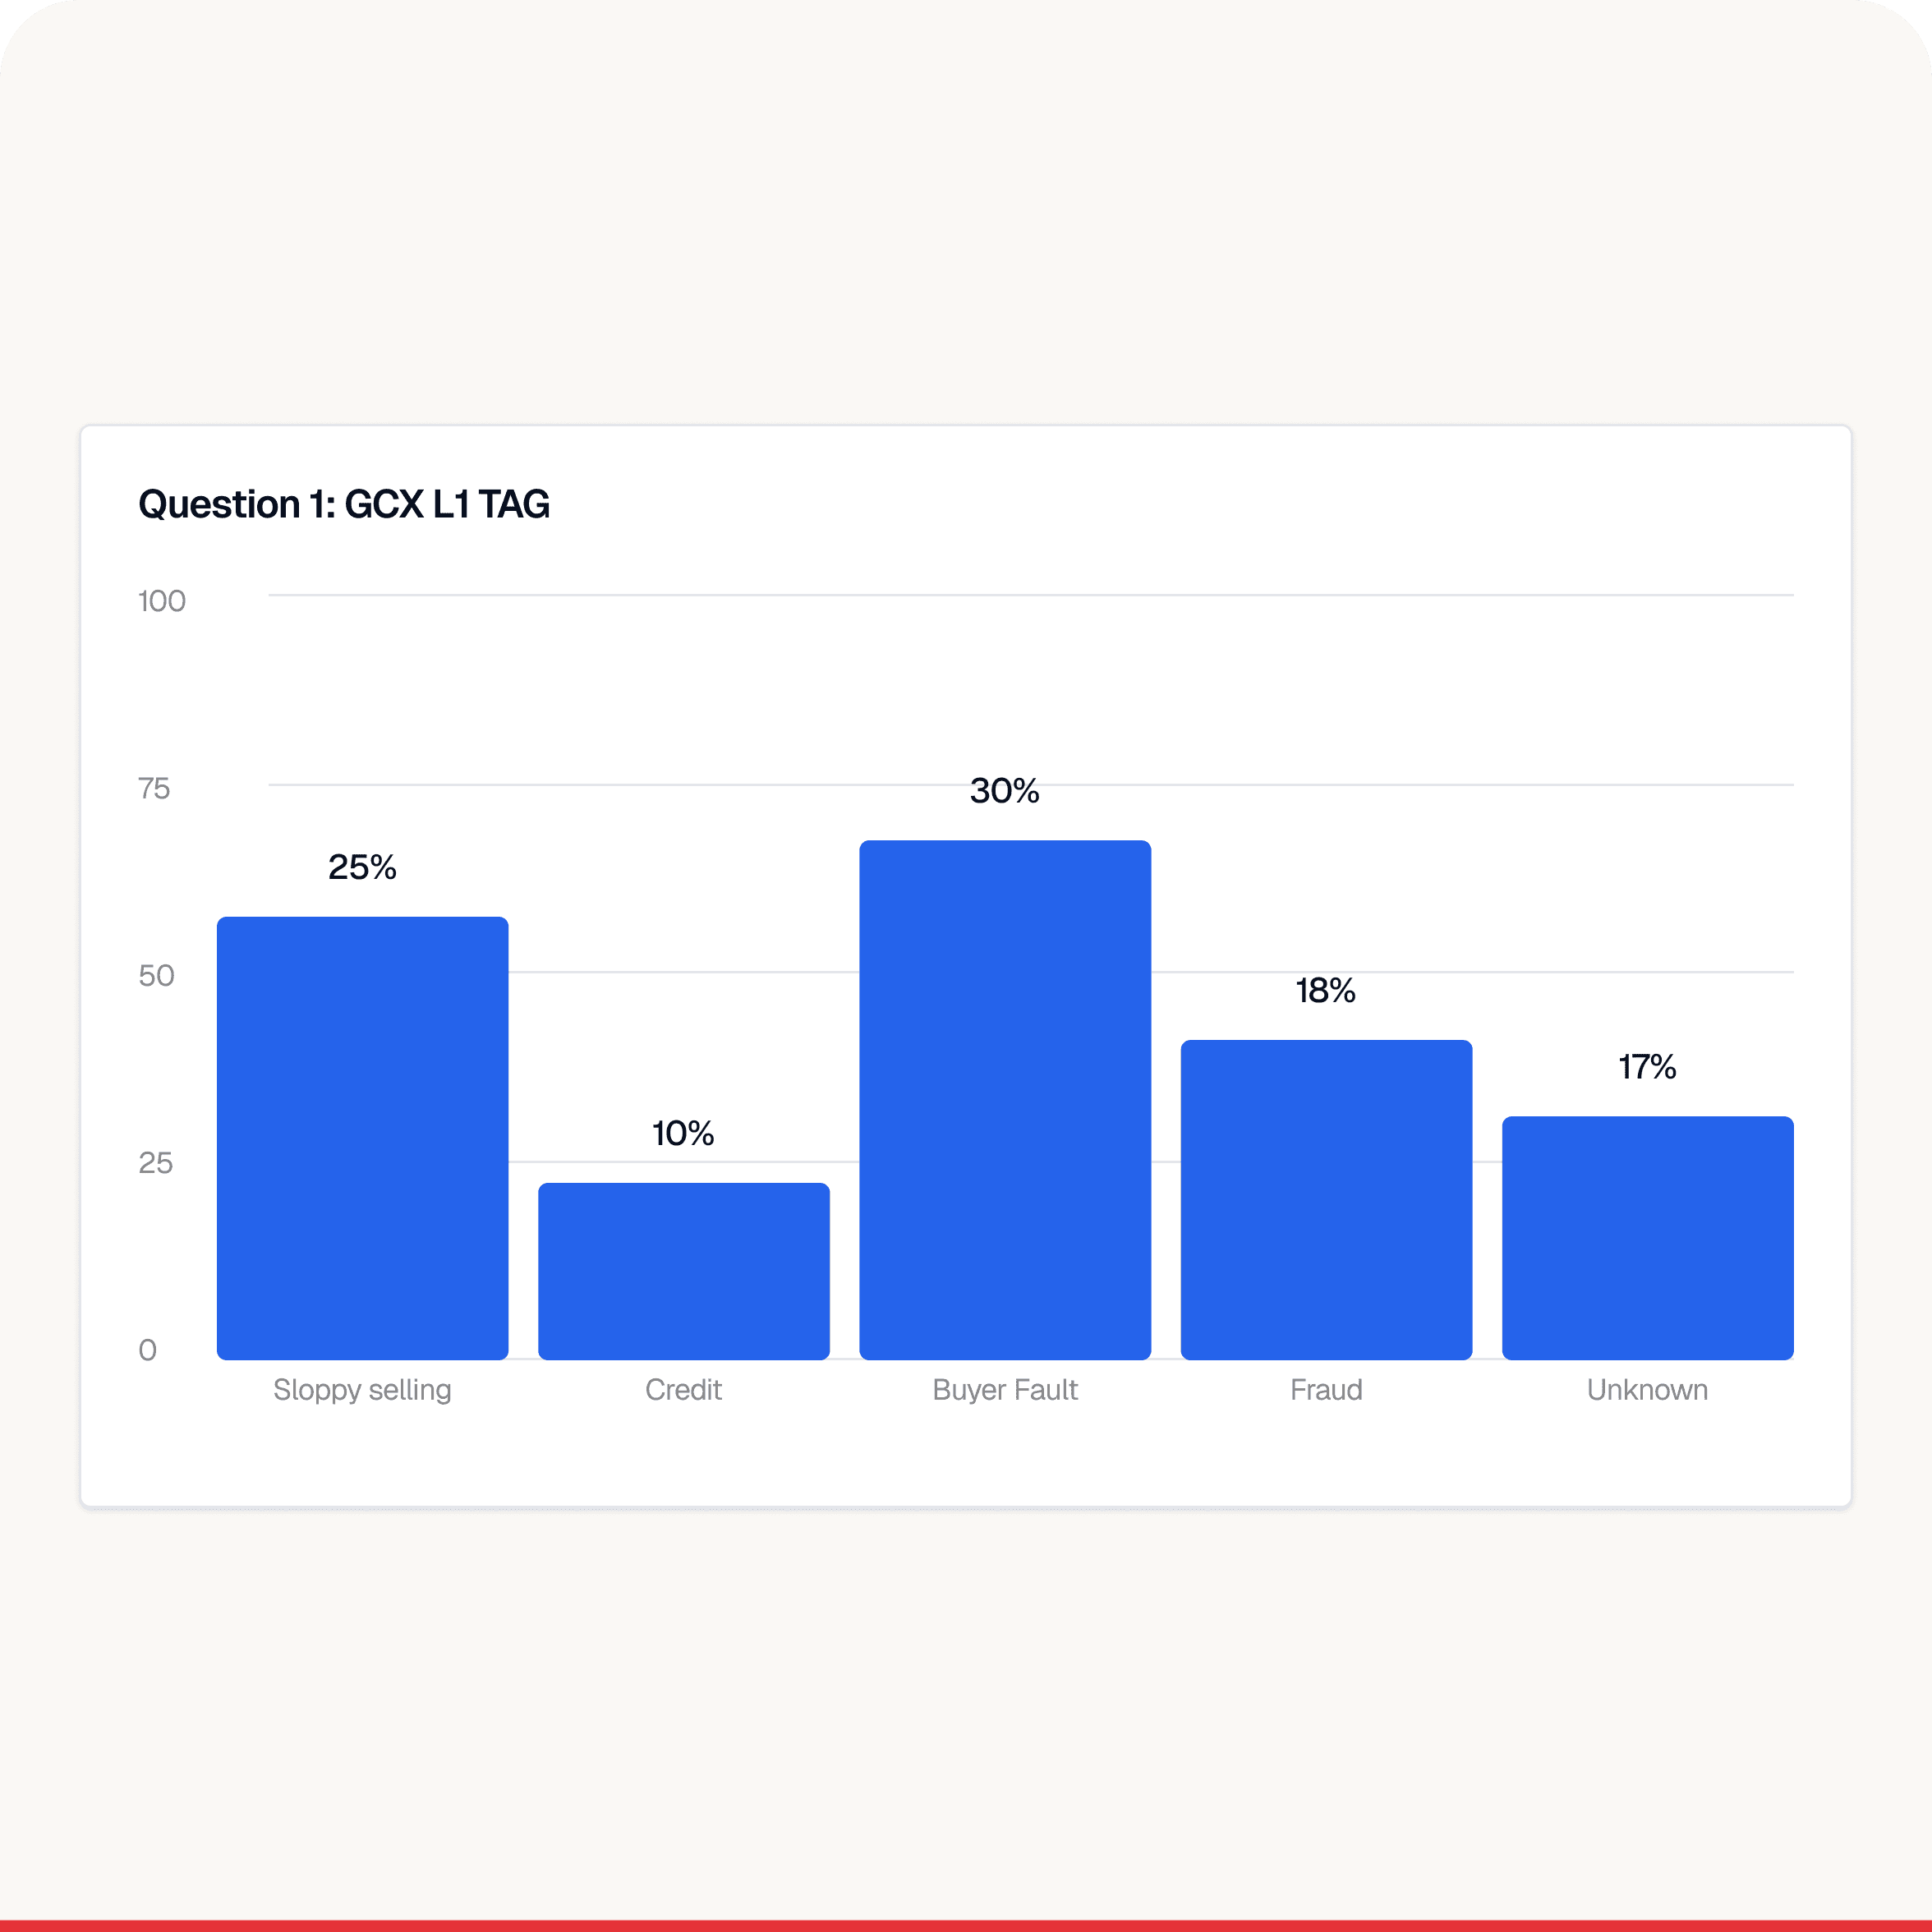
Before
In our initial data visualization design, users struggled to compare current and past job data, making it difficult to spot trends and patterns clearly.
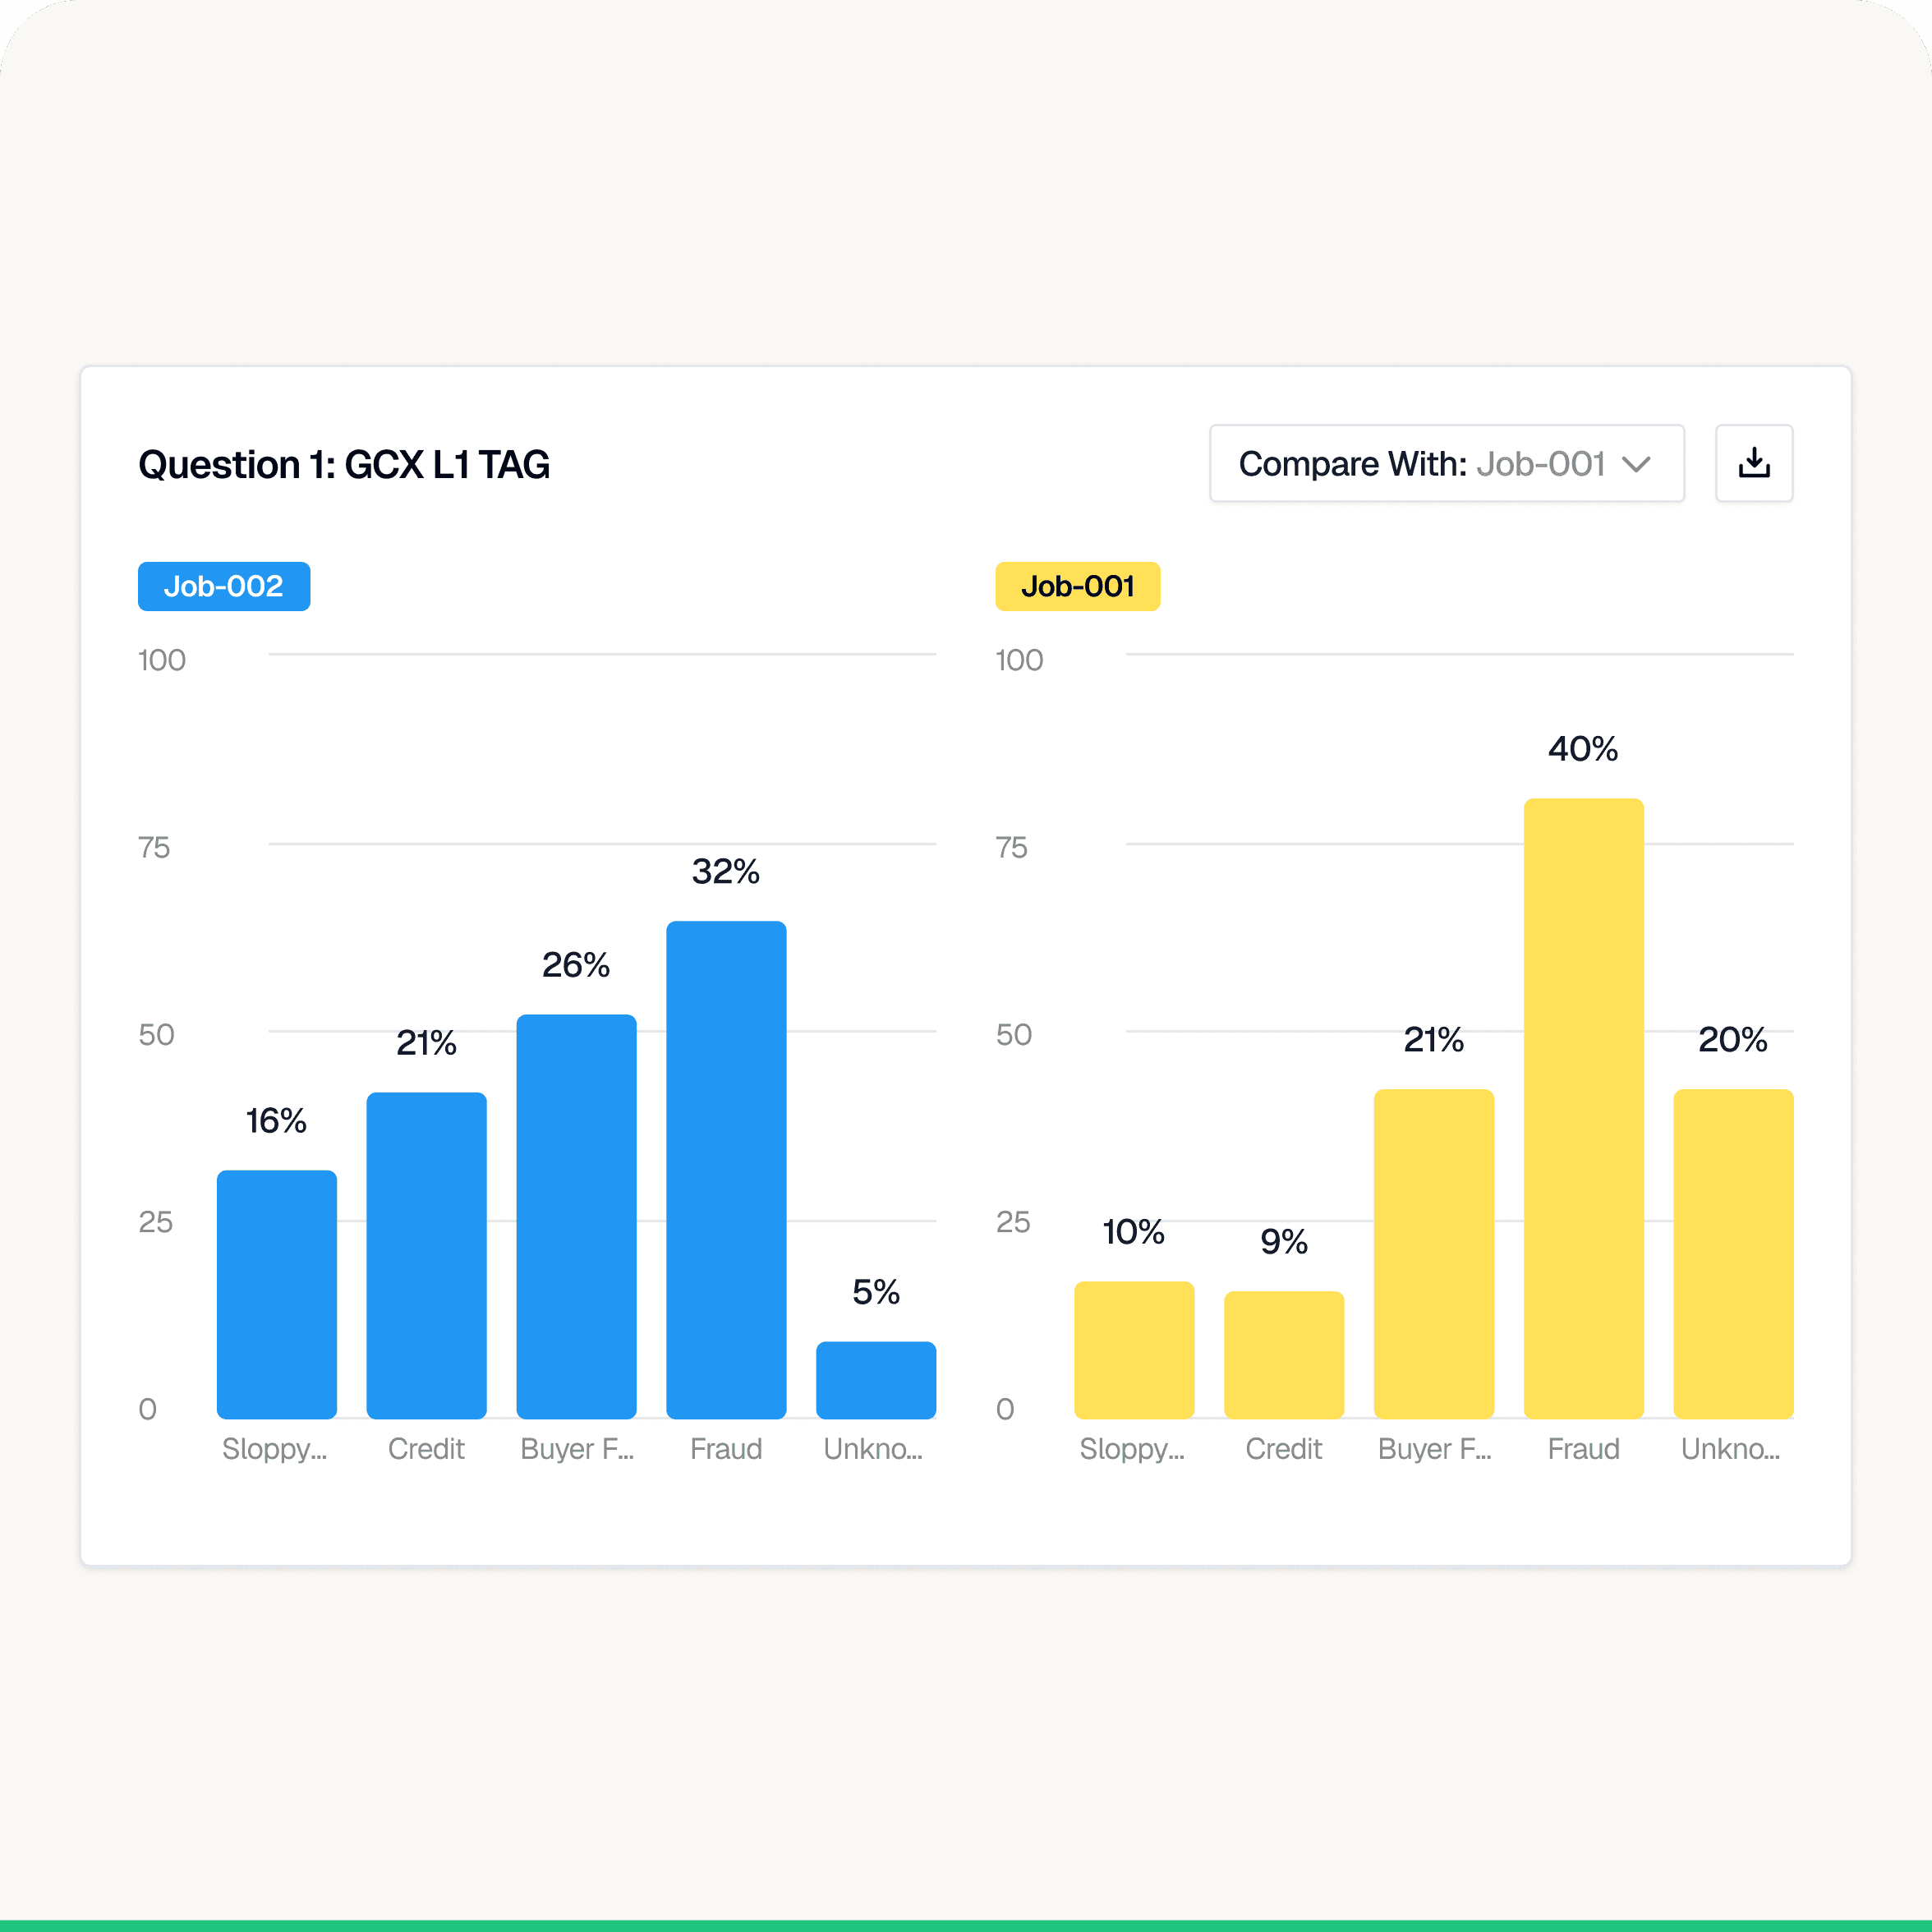
After
We introduced a "Compare With" feature, enabling users to easily analyze trends and changes across different labeling jobs.
Result
Achieving user satisfaction and business goals
With Label Studio, Payment & Risk team transitioned to a fully integrated data labeling platform. Collaborating closely with PM and engineers, we set success metrics and validated our solution’s impact. The tool significantly improved process efficiency and positively impacted employees' daily experiences.
9.8/10.0 satisfaction rate from post-launch survey
Increased from ~28 cases/day to ~50 cases/day per annotator
I could sense that my efforts not only improved the overall process efficiency but also had a positive impact on employee's daily work.